
Catalog of SIP Cores
System on Chip design resources
System on Chip design resources
November 2, 2026 -
Tenstorrent is now serving MiniMax M3.1 Flash on Cloud, with both prefill and decode running on Tenstorrent Galaxy®.
MiniMax released the open weights for MiniMax M3.1 Flash today, and Tenstorrent is now serving it on Cloud, with both prefill and decode running on Tenstorrent Galaxy®.
MiniMax M3.1 Flash runs agent tasks at 70% lower cost than M3, with strong results on coding, computer use, and cybersecurity.
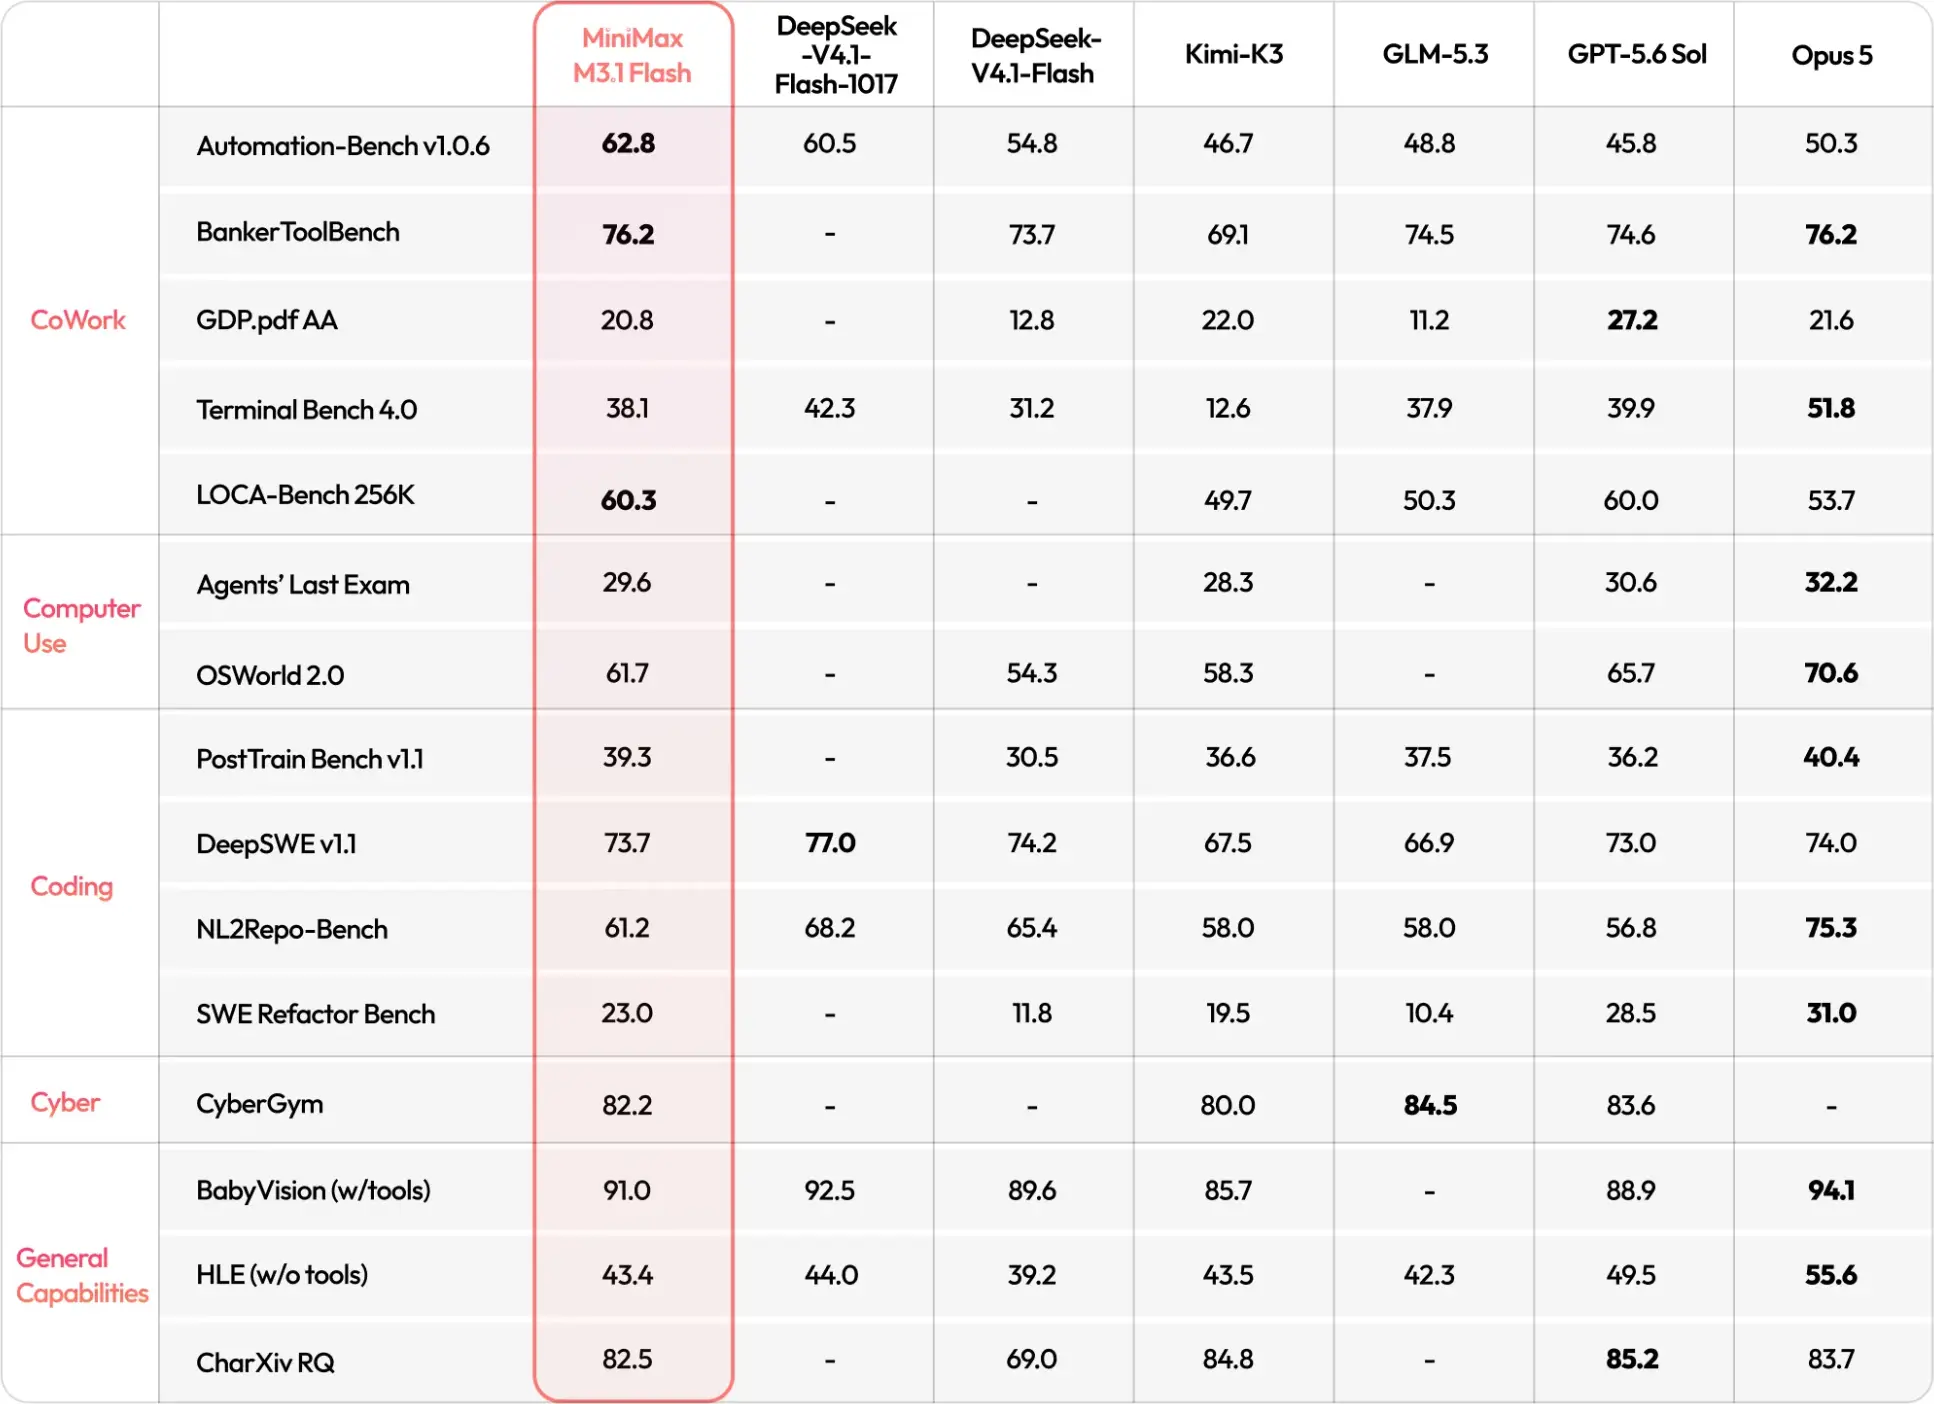
Benchmark results published by MiniMax.
MiniMax M3.1 Flash is built to run agents in production:
Much of MiniMax M3.1 Flash’s speed comes from its architecture and quantization.
MiniMax replaced global grouped-query attention with sparse attention and kept dense MLPs only in the first three layers. Each token reads only part of the context, which reduces compute and memory traffic, especially at long context.
MiniMax was able to quantize much of the model to lower precision data formats while maintaining or improving on the capabilities of the unquantized M3 model. MLP weights, attention weights, indexer, and shared expert were all quantized to MXFP8 while routed expert weights are quantized to NVFP4.
We serve MiniMax M3.1 Flash on a supercluster of Tenstorrent Blackhole Galaxies, with Galaxies split by prefill and decode, so each system can be tuned for its own job:
Tenstorrent tunes on SemiAnalysis’s AgentX coding-agent traces, captured from real multi-turn sessions and subagent fan-out, rather than short chat benchmarks.
MiniMax M3.1 Flash is available on console.tenstorrent.com today. Explore it in the Playground or connect it directly to your agent harness.